
For years, the AI industry has run on one extraordinarily successful idea:
Make the models bigger.
More parameters. More training data. More GPUs. More electricity. More billions.
And it worked.
But new research from MIT gives us a better explanation of why scaling works — and, more interestingly, why simply throwing exponentially more money and computation at LLMs cannot deliver the same gains forever.
That scientific reality arrives at an interesting moment.
AI companies are spending staggering amounts on infrastructure while competing to make AI cheaper. At the same time, some of the executives building the most powerful systems are increasingly warning governments about the dangers of AI and calling for regulation.
Perhaps those things are unrelated.
Or perhaps the people with the best information about the economics of scaling can see the wall before everyone else does.
That second interpretation is speculation. This article explores it as speculation.
Why making an LLM bigger actually works
An LLM needs to represent an enormous number of words, ideas and relationships using a limited number of internal dimensions.
It does this partly through superposition: multiple concepts share the same representational space.
That’s efficient, but overlapping representations interfere with each other. Think of it as noise.
MIT researchers Yizhou Liu, Ziming Liu and Jeff Gore found something remarkably simple about that noise:
interference ∝ 1 / model width
Make the representation twice as wide and this particular interference roughly halves.
Experiments on GPT-2, OPT, Pythia and Qwen produced a scaling exponent of 0.91 ± 0.04, close to the theoretical prediction of 1.
Suddenly one of the mysteries of LLM scaling looks less mysterious.
Bigger models have more representational room. More room means less interference. Less interference means better predictions.
But there is an obvious catch.
You cannot eliminate the same interference twice.
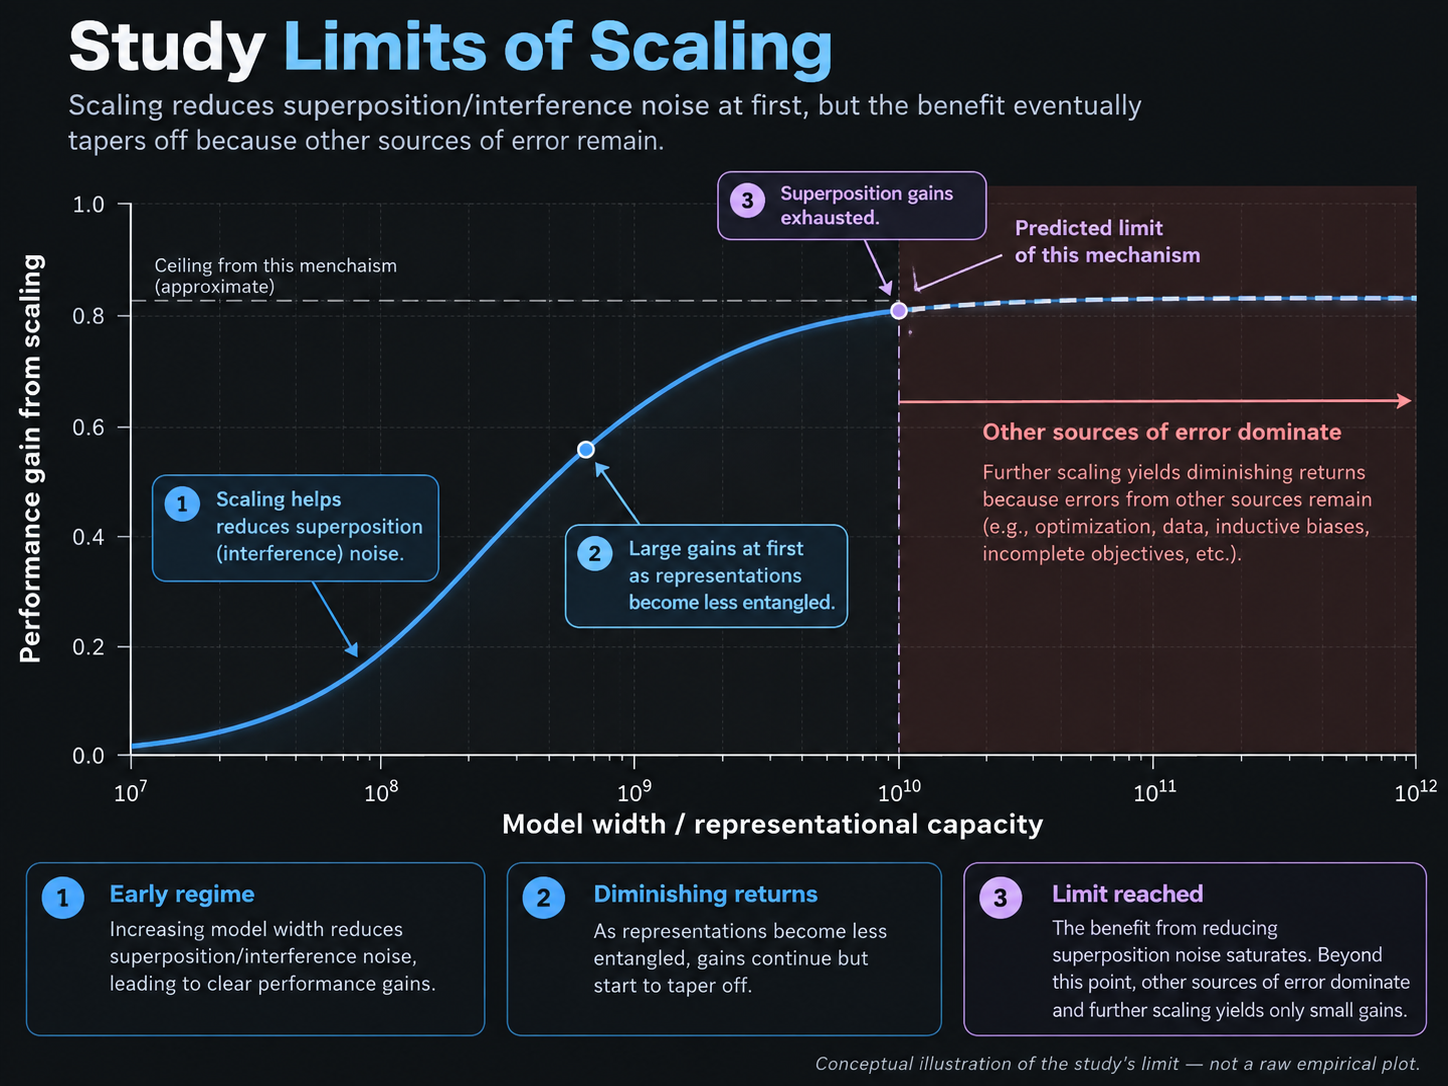
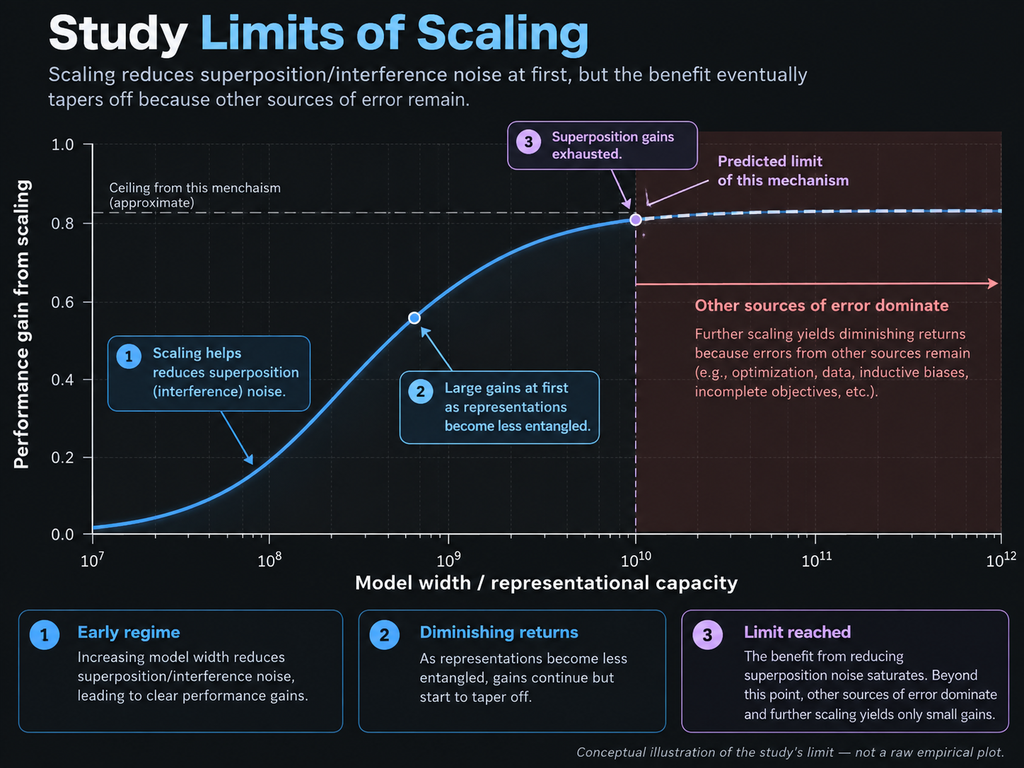
As representations gain sufficient room, there is progressively less superposition noise left to remove. The MIT model therefore predicts that this particular scaling mechanism eventually breaks down.
That doesn’t establish a maximum possible intelligence for AI. Better architectures, algorithms, training methods and other mechanisms can continue improving models.
It does tell us something much more relevant to today’s industry:
“Just make it bigger” is not an infinite strategy.
Unfortunately, bigger becomes fantastically expensive
The second problem is economics.
Classic LLM scaling research found a relationship around:
loss ∝ compute^-0.05
That is a nasty equation if your business plan depends on brute force.
Enormous increases in computation buy increasingly small reductions in loss.
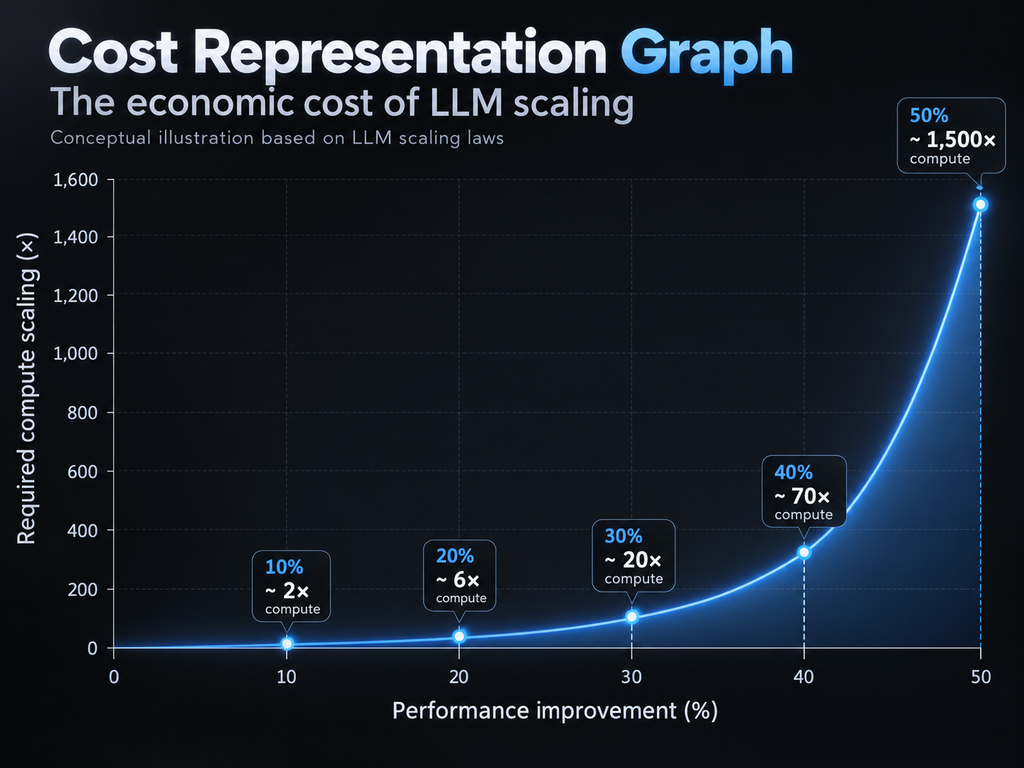
The curve doesn’t technically stop improving. That’s almost the problem.
It keeps offering another small improvement — if you’re prepared to pay an increasingly absurd price for it.
A separate ICLR 2025 study approached the problem from another direction and found that language models could store approximately 2 bits of factual knowledge per parameter in controlled experiments.
These aren’t magical brains whose capabilities expand without physical constraint.
They are information-processing machines with measurable capacity, interference, compute requirements and diminishing returns.
Which brings us to the money.
Now look at what the AI industry is doing
The sums being committed to AI infrastructure are extraordinary.
The Financial Times reported that OpenAI expects around $278 billion in negative free cash flow from 2026 through 2030, alongside roughly $856 billion of projected compute and infrastructure spending.
Stanford’s 2026 AI Index estimates that OpenAI’s compute spending rose from $5.8 billion in 2024 to $16.3 billion in 2025, while Anthropic’s rose from $2.5 billion to $6.8 billion.
And training isn’t the only problem.
Every time somebody asks an AI a question, computation happens again. Successful AI products therefore have a strange property: more customers can mean dramatically more operating expense.
At the same time, competition is pushing AI prices downward.
So the industry is caught between two curves.
The cost of extracting the next improvement rises dramatically.
The market price of providing intelligence faces pressure in the opposite direction.
That is not an especially comfortable place to build a trillion-dollar industry.
And suddenly everyone is worried about AI
Now comes the cynical interpretation.
Executives at leading AI laboratories have increasingly warned about catastrophic AI risks and advocated various forms of government oversight, frontier-model regulation and safety requirements.
Take those warnings seriously. Some AI risks are plainly real.
But we should also be allowed to ask an uncomfortable question:
What if safety isn’t the only thing they are worried about?
Imagine running one of these companies.
You know exactly how much the next generation costs. You know how quickly inference expenses are growing. You have better internal scaling data than almost anyone outside the company. You know whether throwing another order of magnitude of compute at the problem is producing revolutionary capabilities or increasingly expensive incremental improvements.
And then you look behind you.
Open models are improving. Competitors are multiplying. Hardware improves. Techniques diffuse. Researchers reproduce ideas. The price customers expect to pay for intelligence keeps falling.
What would government regulation do?
Potentially, it raises the price of entry.
Mandatory evaluations, licensing, reporting, security requirements and enormous compliance departments are inconveniences for a company already spending tens of billions.
For a new competitor, they can be a wall.
This possibility is not some secret discovery. Economists have a name for the broader phenomenon: regulatory capture. Regulation intended to control an industry can eventually protect its dominant companies from competition.
Recent commentary about AI has explicitly raised this concern.
So consider the alternative interpretation of today’s AI politics.
Perhaps executives genuinely looked at their creations and became frightened.
But perhaps some also looked at their spreadsheets.
Both can be true.
Truth may be another scaling casualty
We cannot see inside the heads of AI CEOs.
We cannot prove that calls for regulation are secretly motivated by deteriorating scaling economics.
But neither should corporate statements of noble intentions be treated as scientific evidence of corporate motives.
These are companies competing for extraordinary amounts of capital, market dominance, prestige and technological power. Their public statements should be examined with the same skepticism we would apply to the oil industry discussing climate policy, banks discussing financial regulation or pharmaceutical companies discussing patent law.
The timing is at least fascinating.
Scientists are beginning to explain why brute-force LLM scaling produces diminishing returns.
Infrastructure spending is exploding.
Loss improvements become progressively more expensive.
AI providers are fighting over prices.
Profitability remains uncertain.
And some of the people with the greatest financial interest in controlling the next stage of AI development are telling governments that the industry needs barriers around it.
Maybe that’s coincidence.
Maybe it’s responsibility.
Or maybe the AI companies have discovered that regulating the race is becoming more attractive just as winning it through brute-force scaling is becoming ruinously expensive.
We don’t yet know.
But when hundreds of billions of dollars, enormous personal fortunes and control of a potentially transformative technology are involved, skepticism isn’t cynicism for its own sake.
It’s due diligence.
Sources
Video — excellent visual explanation of LLM scaling and the MIT research:
https://youtu.be/6xQ8LQfkBg4
Liu, Liu & Gore — Superposition Yields Robust Neural Scaling, MIT / NeurIPS 2025:
https://arxiv.org/abs/2505.10465
Allen-Zhu & Li — Knowledge Capacity Scaling Laws, ICLR 2025:
https://proceedings.iclr.cc/paper_files/paper/2025/hash/26d3c9a66836ded8f34a944f2bfe868e-Abstract-Conference.html
Kaplan et al. — Scaling Laws for Neural Language Models:
https://arxiv.org/abs/2001.08361
Stanford — AI Index Report 2026:
https://hai.stanford.edu/ai-index/2026-ai-index-report
Financial Times — OpenAI’s projected cash burn and infrastructure spending:
https://www.ft.com/content/6011d061-eee3-4193-b3b7-8ee4155f538c
Axios — AI compute economics:
https://www.axios.com/2026/04/02/anthropic-usage-limits-openai
The Guardian — AI slowdown calls, regulation and AI-bubble economics:
https://www.theguardian.com/business/2026/sep/20/ai-slowdown-calls-collapse-of-bubble-datacentre-tech-firms
 FR
 EN
The irony of using AI to make the images didn’t escape me. But I hate doing graphics so I’m pro AI-slave labor.
Prediction: the next COVID/911 will be a ” ROGUE AI CYBERATTACK ” from China/Russia/Iran and the “vaccine” will be letting them have a centralized government-approved AI (others made illegal).
Bonus prediction: government cryptocurrency promoted and slowly becoming mandatory ” for our safety “.